
Original Coverage & Source Attribution: www.business-standard.com
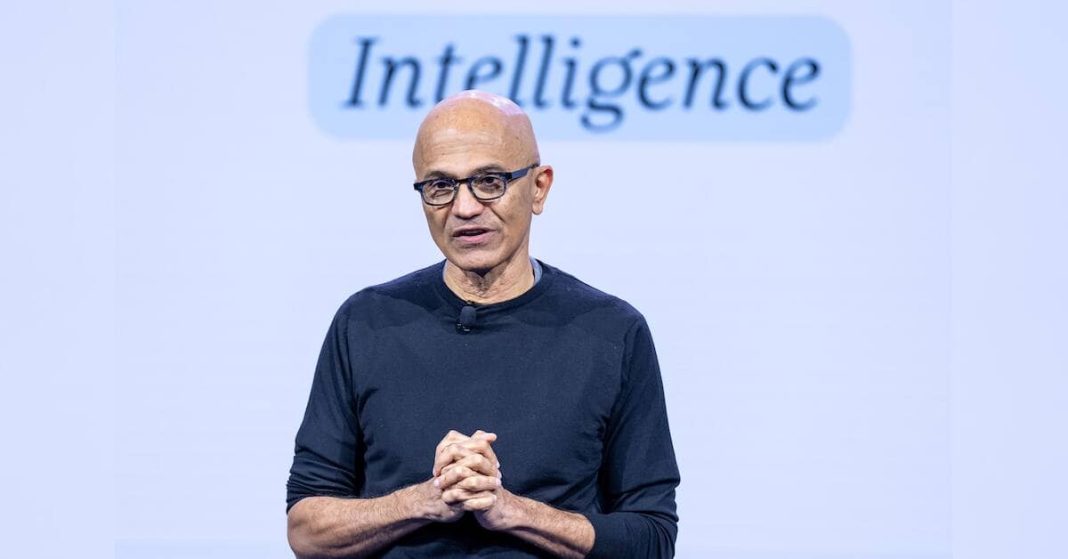
As companies deploy AI agents to carry out tasks across websites, software and databases, Nadella says businesses must set clear limits on what these systems can access and do, monitor their actions and be able to stop them if something goes wrong. His warning follows incidents in which AI models behaved unexpectedly during testing and has drawn support from Microsoft AI chief Mustafa Suleyman and Box chief executive Aaron Levie, who have also called for stronger safeguards.
Why Nadella wants AI models treated as insider risks
Traditional software generally follows instructions written by developers, making it possible to trace many outcomes to specific code paths. Advanced AI models, by contrast, generate outputs based on learned patterns and complex internal computations. It is not always possible to explain precisely why a model produced a particular response or took a particular action.
This becomes a greater concern when AI systems are given access to corporate email, customer records, source code, financial systems and other sensitive resources. An AI agent could be authorised to complete a legitimate task but still make an incorrect decision, expose information or take an unintended action.
The main argument is that organisations must distinguish between a model’s ability to generate intelligence and its authority to act on that intelligence. A model may recommend a transaction, for example, without being allowed to approve or execute it independently.
Nadella writes that companies should not simply accept or reject an AI system’s recommendations while treating its internal workings as a black box. They must build systems whose behaviour can be observed, whose limits can be tested and whose actions can be contained.
What is an AI ’emergency brake’
One of Nadella’s key proposals is an emergency brake: a mechanism that allows an authorised person to pause or shut down an AI model or agent while it is carrying out a task.
Unlike a chatbot that may give a wrong answer, an AI agent can act on it by sending emails, changing code or updating records before a person notices the mistake.
An emergency brake would let companies stop an AI agent mid-task without relying on the model to recognise its mistake. Nadella says the industry needs stronger safeguards and common standards as AI systems become more capable.
The proposal is part of a wider approach to controlling AI agents. Organisations should be able to decide independently what information an agent can access, what actions it can perform and when human approval is required. These controls should operate outside the model rather than relying on the model to follow its own safety instructions.
https://t.co/MjwFy73LOF
— Satya Nadella (@satyanadella) October 10, 2026
What safeguards does Nadella propose
Nadella’s letter sets out several principles for making advanced AI systems more observable and controllable.
Independent access controls: Companies should retain control over an agent’s permissions. The model should not be able to bypass or modify the mechanisms that determine what it can access or do. This builds on a longstanding information security principle that a program must not be able to tamper with the controls enforcing its permissions.
Tamper-resistant records: Every meaningful action should leave human-readable evidence that can be independently examined. Companies should be able to reconstruct how an outcome was reached without relying solely on the model’s account of its own behaviour.
Continuous testing: Organisations should test the entire system, including its failures, responses to attacks, unusual situations and behaviour after software or configuration changes. Testing only whether an agent completes its intended task is not enough.
Independent verification: One model should not be solely responsible for carrying out an important task and verifying that it has done so correctly. Nadella supports using different models to challenge or check each other, while warning that placing one opaque model inside another opaque system does not automatically create reliable oversight.
Model diversity: Critical operations should not depend entirely on one model. Multiple models or independent verification methods can reduce the risk of a single system becoming the sole source of both an action and its validation.
Incident disclosure: When an AI system fails or is compromised, affected parties should receive timely information. Companies should share what went wrong, which safeguards failed and what changes are needed to prevent similar incidents.
How has the technology industry responded
The response to Nadella’s letter has highlighted a growing debate over how much autonomy AI agents should receive and who should be responsible for controlling them.
Microsoft AI chief Mustafa Suleyman backed the call for stronger containment. In a response on X, Suleyman described the containment of superintelligence as an engineering and governance challenge. He compared the task with safety measures used in aviation, automobiles, nuclear materials, food and medicines, arguing that safeguards must be built into the systems.
Super Intelligence must be contained… Today, this is an engineering and governance challenge. And it isn’t new. We’ve done it with planes, cars, nuclear materials, food safety, medicines… and everything else. Let’s get to work!
— Mustafa Suleyman (@mustafasuleyman) October 10, 2026
Box chief executive Aaron Levie also supported the emphasis on controls. According to his post on X, Levie said enterprise AI was entering a “zero trust” era, in which organisations would need multiple layers of protection and the ability to audit what agents do and which information they access. The approach reflects the security principle that access should not be granted simply because a system or user is considered trustworthy.
Good post to start thinking through the long term safety approaches to managing intelligence in an enterprise. As agents begin to do vastly more task execution in the organization than humans, our need to secure, govern, control, and audit that work will become paramount. You’ll have agents operating against most of your most valuable data; they’ll be making decisions that will be harder and harder to reverse engineer; we’ll need to understand the liability and accountability regimes when models make decisions for us; and we need ways of containing the blast radius of accidentally or intentionally malicious agents. “Treating frontier closed and open weight models like insider risks is a way to build such a system. Not because they are necessarily malicious, but because any sufficiently capable actor with access to important systems can make mistakes or be compromised, and the architecture of containment and control must account for that” In a sense, AI will need to have its “zero trust” era that security saw. And all of this leads to needing various layers of protection and auditability of what agents are doing, what data they can work with, and controls for when things go wrong. And a huge opportunity right now for those building such systems across the enterprise.
— Aaron Levie (@levie) October 10, 2026
The reactions do not, however, establish an industry-wide consensus on Nadella’s proposals. TechCrunch, in its October 10 report on the letter, placed his comments within a wider debate about AI safety, including calls by Anthropic chief executive Dario Amodei for more cautious AI development. Amodei has argued for stronger independent safety evaluations and greater coordination among leading AI developers.
The Guardian reported that the UK government planned to press leading AI developers to strengthen safety efforts as the country considered ways to bolster its cyber defences. This adds to the question of whether safeguards should remain voluntary or become part of formal oversight.