Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Fusion reactors mostly come in two flavors: tokamaks and stellarators. A tokamak drives a current through its donut-shaped plasma to help generate the confining magnetic field — a simpler design, but that current is also the main source of plasma instability. A stellarator shapes the entire magnetic field using intricately twisted 3D coils alone, which in principle allows steady-state operation without the current-driven instabilities, at the cost of far harder magnet engineering. Germany’s Wendelstein 7-X stellarator set a world record last year with a 43-second continuous plasma run, lending weight to the stellarator camp’s argument that “physics is no longer the problem — engineering is.” Money is following that thesis across the fusion industry broadly: the Fusion Industry Association says the sector raised $4.48 billion in the year through July 2026, up 69% year-over-year and a record high.
Building Commercial Plants in Tennessee and the UK at the Same Time
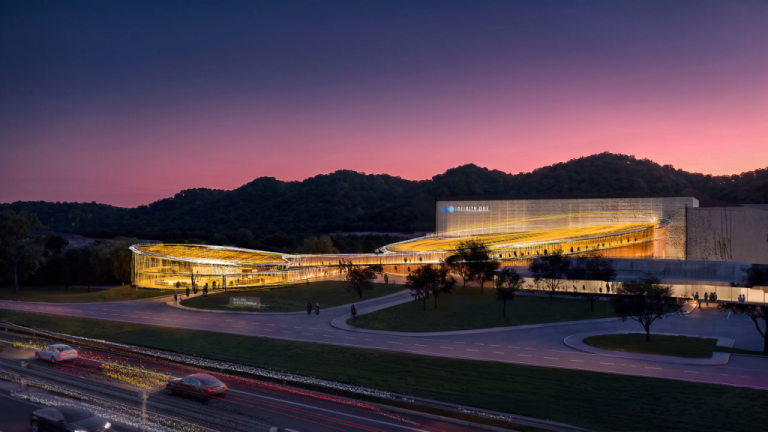
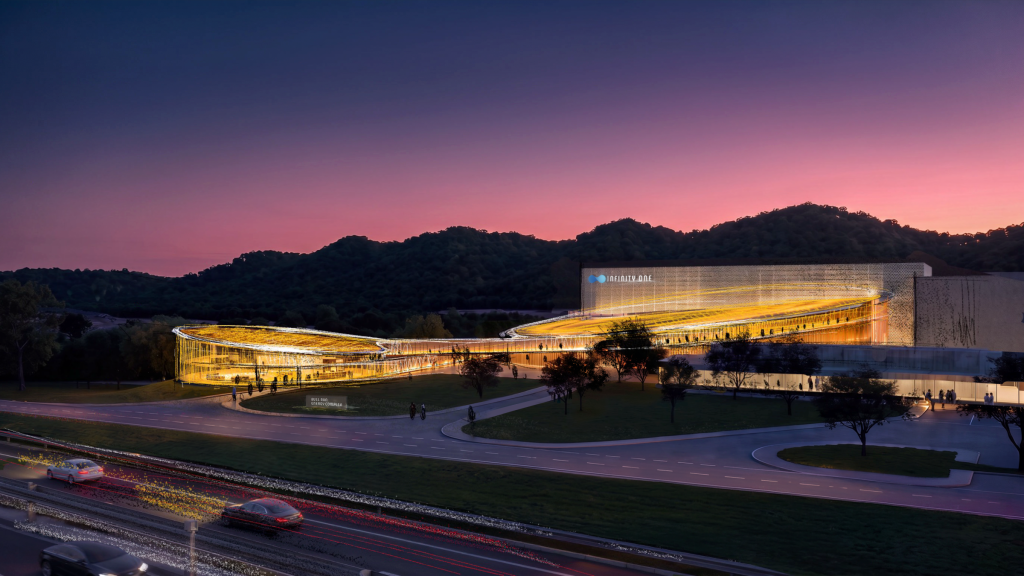
Type One Energy is pursuing stellarator-based commercial fusion power plants under what it calls Project Infinity. It plans to build an engineering prototype, Infinity One, at the Tennessee Valley Authority’s Bull Run site, followed by Infinity Two — a 400 MWe plant the company bills as the world’s first commercial fusion power plant. The new funding supports both the company’s in-house FusionDirect technology program and execution of Project Infinity.
Type One Energy recently received what it describes as the first fusion-plant-specific operating license issued by the State of Tennessee. It’s worth noting this is a radioactive-materials handling license issued under a newly established state regulatory framework, not an NRC-level construction or operating permit — it clears the way toward breaking ground at Bull Run rather than authorizing full construction. Outside the US, the company is also pursuing a second commercial project through the UK Infinity Fusion Consortium, alongside Tokamak Energy, AECOM, Sheffield Forgemasters, and Barclays.
What Type One Energy emphasizes most isn’t the technology itself but its business model. Rather than building every plant from scratch on its own, it pulls in manufacturing, engineering, and operational capability from established energy-industry partners, which it says lets it run multiple plant projects in parallel. Siemens Energy Ventures’ participation in this round, the company says, reflects exactly that kind of industrial partnership.
A General Fusion Alum, This Time With a Stellarator
CEO Christofer Mowry has spent his career moving between nuclear energy ventures. He ran Babcock & Wilcox’s nuclear division before founding Generation mPower, a B&W-Bechtel joint venture aimed at commercializing small modular reactors, in 2011 — a project that folded when Bechtel exited in 2017. That same year he became CEO of General Fusion, a Canadian magnetized-target-fusion company, before founding Type One Energy in 2023. He has also served as chairman of the Fusion Industry Association.
Mowry said: “The breadth and quality of investors in this funding round demonstrates growing support for our strategy to industrialize the commercial deployment of fusion energy. The Series B financing enables us to remain focused on advancing our stellarator technology and Project Infinity design activities, while working with experienced industrial partners to deliver the first commercial fusion power plant at TVA’s Bull Run site.”
Breakthrough Energy Ventures’ Carmichael Roberts said: “Fusion is approaching the point where deployment, not discovery, defines the challenge. Type One Energy brings together the necessary business and technical leadership, optimized stellarator technology and industrial relationships that will help move fusion from breakthrough science to commercial power plants.” Siemens Energy Ventures partner Enrique Gonzalez Zanetich added that “Type One Energy’s pragmatic, execution-focused approach, strong industry and research network, and experienced and knowledgeable team provide a strong foundation for turning scientific progress into a commercially viable energy solution.”
Type One Energy was founded in 2019 and became venture-backed in 2023 with a $29 million seed round, followed by an $82.4 million seed extension in 2024. A $87 million convertible note in January of this year pushed total funding past $160 million; with this $200 million Series B now closed, cumulative funding has passed $400 million.
Competitors: Other Stellarators, and Rival Approaches to Fusion
Type One Energy’s closest stellarator rivals are Europe’s Proxima Fusion and the US’s Thea Energy, both of which have closed large rounds recently — though neither has a comparable model of co-developing a plant with a specific utility at an actual site.
The fusion industry’s best-funded company remains tokamak developer Commonwealth Fusion Systems, which raised another $1 billion in July alone, pushing total funding to $4 billion. Other approaches are drawing serious money too: field-reversed-configuration developer Helion Energy, which has a power purchase agreement with Microsoft, crossed a $15.5 billion valuation this year, while TAE Technologies has kept raising from backers like Google and Chevron. The UK’s Tokamak Energy, which builds compact high-field tokamaks, occupies an unusual dual role as both a rival and a partner — it’s a member of Type One’s UK consortium.
General Fusion, the company Mowry previously led, went through a major restructuring crisis last year before going public on Nasdaq via a SPAC merger as it looks to rebuild. Amid rivals pursuing different reactor designs, different business models, and different fortunes, Type One Energy is leaning hardest on “build it with a utility” as its defining edge.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
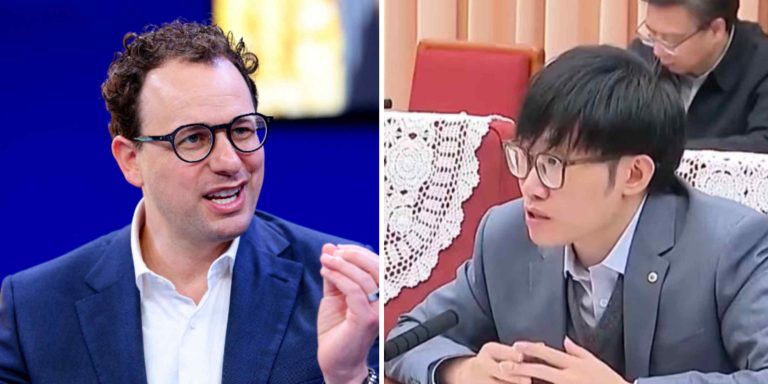
Anthropic CEO Dario Amodei, left, and DeepSeek CEO Liang Wenfeng, whose company has continued churning out new models. (Source photos by Reuters and Nikkei)
ITSURO FUJINO and MANAMI OGAWA
October 7, 2026 00:55 JST
GUANGZHOU/TOKYO — China’s artificial intelligence development drive is showing no signs of slowing, with DeepSeek, Xiaomi and others rolling out models last month despite calls from Anthropic CEO Dario Amodei to slow down as risks mount.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
News breaking of multiple hits in waters London underwriters listed as high risk only last month
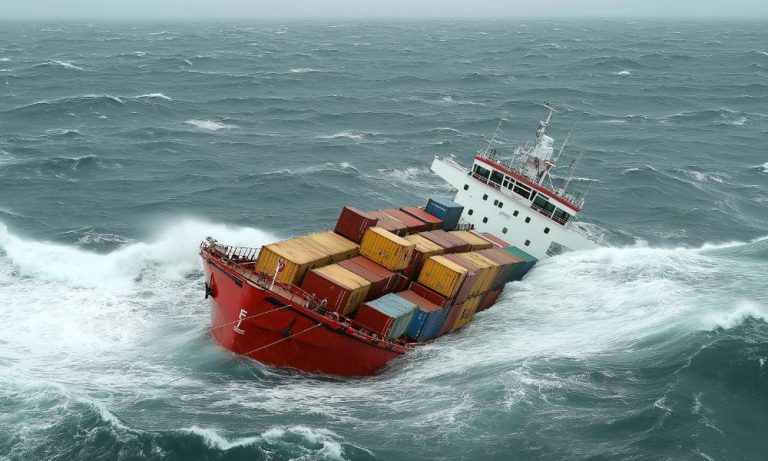
A cargo ship has sunk and a second vessel has caught fire after drone strikes in Bulgaria’s exclusive economic zone (EEZ), in waters the London insurance market added to its Black Sea high-risk area less than three weeks ago.
The attacks took place at about 3am local time on Tuesday (6 October), approximately 128 kilometres off the Bulgarian coast near Byala, Prime Minister Rumen Radev said after an emergency government meeting. Both aerial and sea drones were involved, and their origin has not been established.
The Togo-flagged general cargo ship Alfa Watan sustained critical structural damage and sank. A search is under way for its crew, after a passing ferry found overturned life rafts and life jackets at the scene. The Palau-flagged Able, which was carrying wheat, caught fire. A Bulgarian ferry evacuated its 18 crew – 11 Turkish and seven Indian nationals – two of whom were seriously injured and flown to hospital in Varna.
The strikes were the first on shipping within Bulgaria’s EEZ. Radev said the disruption was driving insurance costs higher and making navigation in the Black Sea extremely difficult.
Strikes land inside newly listed waters
On 16 September, the Joint War Committee (JWC), which is made up of Lloyd’s Market Association syndicate members and London company market representatives, extended its Black Sea Listed Area to cover the whole sea. The coastal waters of Russia and Ukraine were already listed. The territorial waters of Bulgaria, Georgia, Romania and Türkiye remain excluded, but these extend only 12 nautical miles from shore. Tuesday’s strikes, around 70 nautical miles out, fell inside the newly listed area.
A listing does not prohibit voyages, but insurers may require separate war risk cover and an additional premium for transits through the area, priced individually by vessel, route and current risk.
Analysis from maritime security firm Ambrey found that 45 merchant vessels were struck outside the previously listed area in the 12 months to 21 September, compared with none in the preceding 12 months. Thirty-three of those strikes came in the last three months. Ambrey has recorded more than 210 strikes on commercial vessels in the Black Sea between July and the end of September. It expects the conditions behind the JWC expansion to persist for the rest of 2026.
Turkish-owned vessels in the firing line
Both ships hit on Tuesday are Turkish-owned, according to the Equasis shipping database. The Alfa Watan, owned by Mersin-based Baraka Shipping, was built in 1976 and was bound for the Romanian port of Sulina, according to vessel-tracking data. The 1991-built Able is part of Istanbul-based Ocean Eagle’s fleet, according to Türkiye Today. The vessels’ hull war and protection and indemnity (P&I) insurers have not been publicly identified.
The attacks came a day after another Turkish-owned vessel, the Royad Mammadov, caught fire and sank in Romania’s EEZ while carrying Ukrainian corn. Romanian authorities said two people died and 11 crew were rescued. Ukrainian President Volodymyr Zelenskyy attributed the sinking to two Russian drones and said the ship’s captain was among the dead. Romania’s Naval Authority has said the fire followed a suspected drone strike, but has not made a final determination on the cause or named a suspect.
European Commission President Ursula von der Leyen condemned the attacks on civilian shipping.
With three vessels sunk or damaged in less than 24 hours, all outside Russian and Ukrainian waters, hull war and cargo war underwriters, as well as P&I clubs, are likely to face pressure to reprice western Black Sea exposure. The territorial-water carve-outs that still exempt coastal voyages from notification may come under closer scrutiny.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Covering quantum and emerging technologies, Mohib explores the intersection of technology, security, and society. His work also frequently examines surveillance infrastructure and the institutions shaping the digital world. In addition to his work at The Quantum Insider, he co-runs SK NEXUS, an independent technology publication that helps readers understand the technologies shaping their lives.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
WellRithms achieved 30 times faster bill processing by combining AWS services with its deep medical billing expertise. This blog post explores how the company transformed document preparation from a manual constraint into a scalable, AI-powered capability, and the results they achieved.
By continuously investing in AI, WellRithms transitioned from a manual, reviewer-dependent workflow to a scalable bill intelligence solution. With the resulting gains in operational capacity and shorter delivery timelines, the business can onboard new clients without creating equivalent operational constraints.
Leadership quote
“This innovation collaboration represents the next evolution of healthcare payment intelligence. Working alongside AWS, we’re combining intelligent document processing, AI, and our proprietary healthcare expertise to automate one of the industry’s most manual processes. The result is higher-quality data, faster workflows, and a solution that continuously learns and improves as it scales.”
Kelvin Yip, Chief Revenue Officer, WellRithms
The industry problem
Medical billing in the United States is inherently complex, with significant variation in how providers generate and present billing information. Hospitals, clinics, and specialty providers all produce itemized bills in their own way. Examples include different layouts, uneven scan quality, inconsistent line-item structures, and billing conventions that vary from one provider to the next.
This complexity creates more than administrative and operational burdens. The problem also contributes to the unsustainable rise in healthcare spending in the United States. Research estimates that three out of four medical bills contain some error. The Journal of the American Medical Association (JAMA) and the Centers for Medicare and Medicaid Services (CMS) put the figure even higher, estimating that up to 30 percent of all U.S. healthcare spending qualifies as waste. Efforts to increase accuracy and transparency in medical billing have the potential to significantly improve financial and health outcomes for patients and payers across the U.S.
For organizations responsible for reviewing those bills and determining fair reimbursement, that variation increases operational cost. Converting documents into text is only part of the problem. The harder part is turning highly variable medical billing documents into structured, validated, review-ready data that can support accurate, timely, and transparent payment decisions. When information is difficult to interpret and validate, it becomes harder to deliver the fair, accurate, and transparent reimbursement decisions that healthcare stakeholders depend on.
WellRithms and its mission
WellRithms helps organizations bring fairness, accuracy, and transparency to medical bill review. The company combines clinical expertise, AI-powered advanced analytics, and physician-informed review logic. These capabilities support more precise payment decisions and help clients manage complex healthcare costs more effectively.
That work happens at the line-item level, which is a key differentiator for WellRithms. Many bill review approaches evaluate charges in the aggregate and apply broad adjustments across an entire bill. With WellRithms, each charge is analyzed on its own merits. One of many case studies shows that WellRithms reduced a $7.3 million hospital bill by more than $4 million, avoided provider disputes, and offloaded financial risk. That level of precision helps support that reimbursement reflects the care that was delivered, supporting fair and defensible outcomes for all parties involved.
The business challenge
As WellRithms continues to grow, demand for accurate medical bill review continues to increase. Clients expect faster, more consistent results, creating pressure to scale operations without expanding manual document preparation at the same rate. At the same time, healthcare organizations increasingly expect reimbursement decisions that are timely, transparent, consistent, and defensible.
WellRithms’ review system already applied AI-powered advanced analytics and physician-informed logic to medical bills. As bill volume and document variability increased, the document preparation step became a strategic constraint. Complex itemized bills couldn’t be passed directly downstream as raw optical character recognition (OCR) output. They had to be interpreted, structured, normalized, and validated before they could support reliable review by WellRithm’s existing system. The business opportunity was to transform document processing from a manual dependency into a scalable document intelligence capability.
With advances in intelligent document processing (IDP), Amazon Bedrock foundation models, and cloud-based AWS AI services, WellRithms saw an opportunity to combine these capabilities with its medical billing expertise to meet rising client expectations, support future growth, and strengthen its competitive position.
The partnership and solution approach
WellRithms built its IDP solution on AWS. The team used the AWS Generative AI Innovation Center IDP Accelerator as a reference architecture and adapted it to the unique challenges of medical itemized billing. By combining proven cloud infrastructure with AI capabilities on AWS, WellRithms accelerated innovation and positioned the solution for long-term growth. The outcome is a differentiated solution that transforms highly variable medical billing documents into review-ready data. The solution delivers greater scalability, operational efficiency, and reviewer focus on higher-value clinical and billing decisions.
A key decision in the solution design was to move beyond a single extraction approach and instead implement a tiered document processing strategy. Medical bills vary significantly in quality and complexity. They range from clean digital documents to low-quality scans, multi-page itemized statements, and highly variable provider-specific formats. Rather than treating every document the same, WellRithms uses a combination of extraction techniques. Each technique is applied based on the characteristics of the individual bill.
Traditional OCR-based approaches handle simpler and cleaner documents. More advanced AI-powered techniques—including large language models (LLMs) and vision-language models (VLMs)—handle documents that require layout-aware understanding. WellRithms continuously benchmarks these approaches against real-world billing documents to evaluate accuracy, consistency, and cost. This allows the company to determine which extraction method performs best for different document types. The result is a scalable foundation for document intelligence that can improve over time without requiring wholesale changes to downstream review processes.
The transformation
The new document processing capability changed how WellRithms operates; from how bills are prepared to how reviewers spend their time. Before this capability, a complex itemized bill could arrive and immediately require manual attention. A reviewer with knowledge of medical billing codes, provider formats, and clinical context might spend a significant amount of time putting the document into a workable state before any review logic could be applied. As bill volume grew or document quality declined, that preparation burden scaled with it.
With the new adaptive workflow, the same bill moves through an automated process. Documents are routed through different processing paths based on workflow-defined criteria, and the appropriate extraction and structuring approach is applied. By reducing administrative preparation work, experts can spend more time applying clinical, billing, and payment integrity expertise where it creates the greatest value. The operating model is changing as a result. Document handling is no longer a time-consuming process but rather an automated capability that prepares work for human experts.
Results
The AI-powered solution demonstrated strong technical performance and operational readiness during the validation period. The automated workflow successfully processed 2,820 pagesand98,377 extracted lines, validating the solution’s ability to handle complex and data-intensive bills with various lengths.
The results demonstrate a significant transformation in processing efficiency, as shown in Table 1. Under the previous manual workflow, a single bill required approximately 8 hours of human effort. The same bill can now be processed in 15–20 minutes of expert review time with an average AI processing time of 70.1 seconds per bill. This represents approximately 30 times faster processing capability (Table 1). The turnaround time decreased from 5 business days to 1 business day (5 times faster), supporting faster client delivery and improved client experience.
Table 1. The key performance improvements provided by AI on bill processing.
Business outcome
Before AI
AI performance
Business impact
Page processing volume
Manual extraction from bills into Excel
2,820 pages processed
Validated capacity to handle increasing bill volume
Information extraction scale
Manual line-by-line data entry
98,377 lines processed
Demonstrated high-volume structured data extraction
Manual processing effort
Approximately 8 hours per bill for data entry
Reduced to 15–20 minutes per bill for expert review (with 70.1 seconds average AI runtime per bill)
Approximately 30 times faster processing capability
Turnaround time
Up to 5 business days
Up to 1 business day (with minutes-level AI processing)
Supports faster client delivery and improved scalability
Current page processing throughput
Manual page review and keying
1,167 pages/hour
Supports high-volume bill processing
Data processing speed
Manual extraction workflow
3.1 seconds per page with AI
Provides approximately 9.5 times processing capacity buffer*
*Assumes continuous AI processing time and excludes human review and quality assurance.
The validation also demonstrated that AI performance remains strong across various bill quality levels and page lengths. The current page processing throughput is 1,167 pages per hour. An AI processing speed of 3.1 seconds per page provides a buffer of approximately 9.5 times processing capacity, assuming continuous AI processing time and excluding human review and quality assurance. These results demonstrate that the AI-powered solution can handle significantly higher bill volumes without linear increases in operational staffing resources.
Broader business impact
The strategic implication of this transformation extends beyond operational efficiency. The AI solution is making document preparation more scalable and adaptive. Wellrithms can now process higher bill volumes and more diverse provider formats while maintaining client-expected quality. Specialized reviewers can spend more of their time where their expertise has the highest impact: clinical validation, billing exceptions, judgment-based analysis, and payment integrity review.
The immediate result is a more scalable and defensible operating model. In this model, document intelligence amplifies existing expertise. Human judgment is focused on the decisions that create the most value. The model strengthens the consistency, transparency, and defensibility of the reimbursement process.
Looking ahead
Adaptive document processing is a foundation to build on. Where today’s solution transforms documents into structured data, the next generation will help reviewers evaluate that information in a broader billing context.
With more reliable, structured data flowing into review workflows, WellRithms is positioned to layer deeper intelligence on top of that data. The team is exploring advanced agentic architectures capable of reasoning across documents, identifying exceptions, validating extracted information, and assisting reviewers throughout the full bill review lifecycle.
With continuous innovation in technology, WellRithms’ mission remains unchanged: helping organizations make fair, accurate, and defensible reimbursement decisions at scale.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Aldrich Services LLP, an Oregon-based financial services firm that is part of the Aldrich Group of Companies, disclosed a data breach that occurred in August 2026.
The breach was disclosed to the attorneys general offices of California and Massachusetts on Oct. 1, 2026. Aldrich Services began notifying consumers by written notice on Oct. 1, 2026.
The breach began when an unknown individual gained access to an employee email account at Aldrich Services. The company became aware of suspicious activity related to the account and took steps to secure it.
An investigation was launched to confirm the security of the company’s email environment and to determine what may have happened. The investigation found that the unknown individual had access to the employee email account from Aug. 22, 2026, to Aug. 23, 2026.
After securing the account, Aldrich Services conducted a review of the data that may have been accessible through the compromised email account. On or around Sept. 28, 2026, the preliminary review was completed.
The review determined that the types of personal information potentially exposed included names, Social Security numbers and financial account information.
Aldrich Services’ response to the breach
The company is offering affected individuals complimentary credit monitoring services through Experian. The company additionally encouraged consumers to remain vigilant against incidents of identity theft and fraud over the next 12 to 24 months.
Individuals with questions can contact the company’s dedicated call center at 1-833-931-5155, available from 6 a.m. to 6 p.m. Pacific Time, excluding major U.S. holidays. Individuals may also write to Aldrich Services LLP, 5665 Meadows Rd. #200, Lake Oswego, OR 97035.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Engineers increasingly use coding assistance tools to accelerate their development workflows. Today, Amazon SageMaker AI optimized generative AI inference introduces the aws-ai-ml skill, available through the Agent Toolkit for AWS. This skill gives coding agents like Kiro, Claude Code, and Codex deep expertise in inference optimization and benchmarking. Install the skill, and your existing agent can benchmark endpoints, recommend deployment configurations, compare performance runs, and generate executable SageMaker Python SDK v3 code on your behalf. The aws-ai-ml skill is a toolkit that plugs into any coding agent that supports the Model Context Protocol (MCP), turning it into a SageMaker AI inference optimization expert.
In this post, we walk through what the skill enables, how to set it up, and how it helps you move faster from model to production.
The challenge: Bridging intent and infrastructure
Amazon SageMaker AI supports serverful hosting across real-time, batch, and asynchronous modes. It offers on-demand and reserved capacity, heterogeneous instances, virtual private cloud (VPC) isolation, automatic scaling, and integration with every SageMaker AI training path. The surface area is broad and deep, but most engineers do not arrive knowing which instance family or serving container will best serve their needs. They arrive with a use case: a performance target they want to hit, a cost envelope they need to stay within, or a model they need to evaluate before committing to production.
The agentic experience for SageMaker AI optimized generative AI inference closes this gap. You tell the agent what you want to accomplish, and it produces executable SageMaker Python SDK v3 code that you can review, modify, and run in your own environment. The agent asks targeted clarifying questions, generates code grounded in real benchmarks and measured performance data, and adapts to your business constraints the way a solutions architect would.
Throughout, you stay in control. Every step is visible in real time and expressed as code you can read and question. Nothing happens behind an opaque UI.
Getting started
You can install the aws-ai-ml skill through the Agent Toolkit for AWS on your local machine, or use it within an Amazon SageMaker Studio JupyterLab space. Either way, you can go from zero to a working conversation in 10 minutes.
Option A: Use with any coding agent (Kiro, Claude Code, Codex, or any MCP-compatible agent)
Step 1: Install the Agent Toolkit for AWS. If you haven’t already, set up the Agent Toolkit. This requires AWS Command Line Interface (AWS CLI) 2.35+ and uv installed.
aws configure agent-toolkit
This auto-detects your agents, installs skills, and configures the AWS MCP Server. For agent-specific setup (plugin install commands, MCP config), see the Agent Toolkit for AWS getting started guide.
Step 2: Install the aws-ai-ml skill. Add the SageMaker AI optimized generative AI inference skill to your agent:
Step 3: Confirm and begin. Open your coding agent’s chat panel and ask: “What skills are available?” You should see aws-ai-ml listed. After you confirm, describe your intent in natural language. Your coding agent now has SageMaker AI inference optimization expertise built in.
Prerequisites: Your AWS credentials must have permissions to call SageMaker AI APIs (creating endpoints, running benchmark and recommendation jobs). The skill generates code that runs under your credentials. No additional AWS Identity and Access Management (IAM) configuration is needed for the skill itself.
Note: For Kiro and Claude Code, agents can discover skills at runtime. They can search for and load skills on demand through the AWS MCP Server, without any local installation. Ask your agent: “Search for AWS skills related to databases.” Refer to the readme for discovering skills at runtime.
Option B: Use within Amazon SageMaker Studio
If you prefer to work inside a managed JupyterLab environment, you can use the skill in Amazon SageMaker Studio with a pre-configured image.
Step 1: Open Amazon SageMaker Studio. Navigate to Amazon SageMaker Studio in your target AWS account and AWS Region. Select your Studio domain and launch the Studio IDE from your user profile.
Step 2: Create a JupyterLab space. From the Studio landing page, choose JupyterLab, then choose Create JupyterLab space. Name the space (for example, my-inference-opt) and keep the sharing setting Private (skills only sync on private spaces). Under the Image menu, select the image that includes the SageMaker AI optimized generative AI inference skill. This image ships pre-configured with the aws-ai-ml agent skill and all necessary dependencies. Choose Run space and wait for it to boot (5–10 minutes the first time).
Note: Use a fresh space. A reused space with a locally modified skill version may not pick up the pre-configured image.
Step 3: Open JupyterLab and launch a terminal. After the space boots, open JupyterLab and choose Terminal.
Step 4: Authorize your coding agent. In the terminal, authenticate with your coding agent using your identity provider. For example, with Kiro:
kiro-cli login --license pro --identity-provider --region us-east-1 --use-device-flow
Step 5: Confirm and begin. Open your coding agent’s chat panel and ask: “What skills are available?” You should see aws-ai-ml listed. Once confirmed, describe your intent in natural language.
Troubleshooting:
If the agent reports no skills are available, verify that your space is set to Private. You can also check from the terminal:
If that directory is empty but /etc/sagemaker/skills/ contains the skill files, run restart-jupyter-server, refresh the page, and retry.
What you can do
The agentic experience covers the following capabilities across the inference optimization lifecycle. You don’t need to know which capability to invoke. Describe what you want, and your agent figures out the next step or asks clarifying questions if anything is unclear.
Benchmark an existing endpoint
If you already have a model deployed on a SageMaker AI endpoint, you can ask the agent to benchmark it. Tell the agent which endpoint you want to test, and it generates a Python notebook that runs a load test using the Workload.synthetic() and start_benchmark() APIs from the SageMaker Python SDK.
Before running any benchmark, the agent confirms that your endpoint is safe to load-test, because benchmarking drives real traffic to a live endpoint.
When the benchmark completes, you get a quantitative performance report with:
Throughput: requests per second, output tokens per second.
Concurrency: number of simultaneous requests supported.
These are measured values from real load on real infrastructure, not estimates. The agent also recommends improvement mechanisms (such as prefill decoding) to boost performance.
Example prompt:“Benchmark my Llama endpoint on SageMaker AI.”
Find the right instance type for your model
If you have a model and need to find the right instance type to deploy it on SageMaker AI, tell your agent. It doesn’t matter where your model lives or how you obtained it:
Fine-tuned or custom model in Amazon Simple Storage Service (Amazon S3): You trained or downloaded a model and stored it in S3. Provide the S3 URI and your optimization goal. Example prompt: “I want to find the cheapest instance type to deploy my fine-tuned model on SageMaker.”
Publicly available foundation model from Amazon SageMaker JumpStart: You want to deploy a foundation model (FM) from the JumpStart catalog then provide the model ID. Example prompt: “Find the best instance for model huggingface-reasoning-qwen3-8b on SageMaker AI.”
Model on the Hugging Face Hub: You want to use a model hosted on Hugging Face. Provide the model name. For gated models (such as Llama variants), your agent surfaces the license terms and asks you to accept them and provide your Hugging Face token. Example prompt: “I want to deploy a Llama model from Hugging Face Hub. What’s the cheapest option?”
In every case, your agent generates code that evaluates your model against candidate instances and configurations, then presents ranked deployment options with concrete performance metrics: throughput, latency percentiles, time-to-first-token, and concurrency. You choose based on your cost and performance requirements.
Compare benchmark runs
If you ran multiple benchmarks (for example, before and after a configuration change, or across two instance types), you can ask the agent to compare them. Provide the two benchmark job names, and the agent generates a comparison that computes deltas across key metrics: throughput, latency percentiles, and time-to-first-token.
The results show percentage changes where positive means better, giving you a single, interpretable summary of whether your change improved performance, degraded it, or had no meaningful effect.
If one of the benchmark runs doesn’t exist, the agent offers to run it first before proceeding with the comparison.
Example prompt:“I have two benchmark runs and I want to compare them. Which one is faster?”
Benchmark results
This table compares two deployed models on the same benchmark workload (512/256 tokens, concurrency 4). The Δ% column shows how much faster Model B (Qwen3-8B) is than Model A (Qwen3-1.7B) on each metric. A positive value means Model B is better.
Metric
Qwen3-1.7B (Model A)
Qwen3-8B (Model B)
Δ%
Output token throughput
188.2 tokens/s
271.2 tokens/s
+44.1%
Per-user throughput
47.5 tokens/s
69.4 tokens/s
+45.9%
Request throughput
0.736 req/s
1.08 req/s
+46.7%
Inter-token latency
20.9 ms
14 ms
+33.0%
Request latency
5,382 ms
3,658 ms
+32.0%
Time to first token
67.5 ms
166.3 ms
−146.5%
The two models run on different hardware. Qwen3-8B uses a 4-GPU ml.g5.12xlarge (4x A10G), while Qwen3-1.7B uses a single L4 GPU (ml.g6.4xlarge). The deltas reflect approximately 4x the compute, not just the models themselves.
The takeaway: Qwen3-8B delivers approximately 44–47 percent higher throughput and lower end-to-end latency, largely thanks to the additional GPU compute. Qwen3-1.7B wins only on time-to-first-token, the expected advantage of a smaller model on a single GPU.
Putting it all together
You don’t need to memorize capability names or know which workflow to request. The following table shows how common requests map to outcomes.
You say
What you get
“I already deployed a model and want to know how fast it is.”
Quantitative performance report: throughput, latency percentiles, concurrency metrics from real load.
“I have a model in S3 and I don’t know what instance to deploy on.”
Ranked deployment options with cost, throughput, and latency for each candidate configuration.
“I want to deploy a JumpStart model and find the cheapest instance. I only have the model ID.”
Ranked deployment options, no S3 staging required. Gated-model alternative surfaced if needed.
“I ran a benchmark before and after a change. Which one is faster?”
Percentage change across all metrics indicating improvement or regression.
“I want to optimize a Llama model from Hugging Face Hub.”
License surfaced, model staged to S3, then standard recommendation output.
If your request spans multiple capabilities (for example, staging a Hugging Face model and then getting deployment recommendations), the agent chains them naturally within the same conversation.
What to expect from the agent
Your agent, equipped with the aws-ai-ml skill, follows a few behaviors that make the experience predictable and safe:
It asks for what it needs. If information is missing (such as an endpoint name or S3 URI), the agent asks you to provide it rather than guessing.
It confirms before impactful actions. Before running a benchmark that drives real traffic to a live endpoint, the agent warns you about the impact and asks for explicit confirmation.
It tells you when something is out of scope. If you ask for something the agent can’t do (such as deploying a model), it explains what it can offer instead, such as generating the deployment configuration that you need.
It generates SageMaker Python SDK v3 code. Every output is executable code you can inspect, modify, and run in your own environment.
Clean up
To avoid ongoing charges, delete the resources you created:
Conclusion
The aws-ai-ml skill for Amazon SageMaker AI optimized generative AI inference turns your existing coding agent into a SageMaker AI inference optimization expert. Whether you need to benchmark a live endpoint, find the cheapest instance for your model, compare configurations, or stage a Hugging Face model for evaluation, you describe what you want and your agent delivers measurable results.
To get started, install the skill through the Agent Toolkit for AWS and add it to the coding agent you already use, or launch a pre-configured JupyterLab space in Amazon SageMaker Studio. For more information, see the Amazon SageMaker AI documentation.
About the authors
{
“@context”: “https://schema.org”,
“@type”: “NewsArticle”,
“headline”: “New agent skill: Amazon SageMaker optimized generative AI inference for your coding agent”,
“datePublished”: “2026-10-05 17:23:00”,
“image”: “https://d2908q01vomqb2.cloudfront.net/f1f836cb4ea6efb2a0b1b99f41ad8b103eff4b59/2026/09/29/ML-21968-featured-image.png”,
“author”: {
“@type”: “Organization”,
“name”: “Pune.Media Editorial Desk”,
“url”: “https://pune.media”
},
“publisher”: {
“@type”: “Organization”,
“name”: “Pune.Media”,
“logo”: {
“@type”: “ImageObject”,
“url”: “https://pune.media/wp-content/uploads/logo.png”
}
},
“isBasedOn”: “https://aws.amazon.com/blogs/machine-learning/new-agent-skill-amazon-sagemaker-optimized-generative-ai-inference-for-your-coding-agent/”,
“mainEntityOfPage”: “https://aws.amazon.com/blogs/machine-learning/new-agent-skill-amazon-sagemaker-optimized-generative-ai-inference-for-your-coding-agent/”,
“creativeWorkStatus”: “Editorial-assisted Curation”,
“comment”: {
“@type”: “Comment”,
“text”: “This article was curated, verified, and structured under organizational human editorial guidelines by the Pune.Media Editorial Desk.”
}
}
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Also read: OpenAI agent sparks chaos again; Wikimedia flags millions of requests, unauthorised edits
Why has voice become crucial to interact with agentic AI?
According to MacDougall, the case starts with speed and context. “You can talk quicker than you type, about 3 times, 4 times quicker,” he said. “It’s just simpler to be able to talk, and you will be able to give the agent much more context when you talk, because you’re not editing yourself.”
He also suggested a simple test: build a PowerPoint presentation with an AI agent twice, once using test prompts and once by giving voice prompts. He said the spoken version gives a better outcome. This shift has become the reason why major AI companies have started to integrate voice into their products.
Accuracy is the key
Voice commands also demand accuracy, as AI will only work if the agent hears you properly. MacDougall said this is where Jabra’s new Evolve3 headset range comes in. He claimed that the headset offers 98% accuracy in Microsoft Copilot, compared to 60% on some consumer devices.
He revealed that this was possible because of Jabra’s signal-processing heritage and an on-device deep neural network (DNN). This technology helps separate the wearer’s voice from background noise. MacDougall called Evolve “the world’s most popular enterprise headset.”
Must read: Around 75% of firms in India are still not using artificial intelligence, with AI adoption remaining uneven across the economy : World Bank
MacDougall also revealed Jabra uses AI, and he pointed to three ways:
To improve audio and video performance in its hardware;
To link its devices to an AI assistant or large language model a customer chooses; and
Internally, in R&D and operations
However, the company has no plans to build its own AI models, as it currently focuses on seamless integration based on its customers’ preferences.
From desk phones to AI agents
When asked about the idea behind Evolve3 and the PanaCast U30 range, MacDougall traced the shifts in workplace communication from desk phones in the 1990s, PC-based unified communications from the mid-2000s, to the rise of hybrid work during the pandemic. “Most people work in three different places during the course of a week,” he said.
Due to the reason, he highlighted that enterprise products should work across different work environments, rather than being limited to a traditional office. He highlighted the shift that businesses are now looking for AI-ready devices that are practical, comfortable, and secure enough for everyday use.
For Jabra’s PanaCast U30 room system, MacDougall says simplicity is the biggest priority; the system should be easy for businesses and employees to set up and use without unnecessary complexity.
“What customers care about is rooms that are easy to manage and deploy.” The aim, he said, is that “you can just plug a cable in, and it works straight away.”
India takes the first mover’s advantage
MacDougall also shed light on the future of enterprise AI, saying that he expects teams to include both people and AI agents. “AI workflows will fundamentally change the way we all work,” he said. However, he expressed concerns over data privacy for companies.
Talking about the Indian market, MacDougall said, “India is an important market for us. It’s one of our fastest-growing markets,” with demand coming from multinationals, global capability centres (GCCs) and local companies.
According to him, Indian companies are buying audio gear for human-to-human collaboration, but he also said that conversations about AI-ready workplaces are increasing. MacDougall pointed to an internal Jabra study that stated: “In India, knowledge workers are using AI tools more commonly than in the US and Germany and actually all across the world.”
“We expect India to be in the first wave of markets,” he said, when asked where voice AI will take hold in the workplace.
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
Original Coverage & Source Attribution: pluang.com
Amazon commits $200B to AI and infrastructure, boosting investor confidence despite rising debt.
Amazon announced a massive $200 billion investment in 2026 focused on AI infrastructure, custom chips, robotics, and satellites, signaling strong growth potential. Key profit drivers like AWS, advertising, and retail continue to expand, with AWS alon…
Editorial Disclosure: This article is an editorial-assisted curated synthesis of verified global coverage. The original source reporting has been analyzed, structured, and compiled by Pune.Media’s Editorial Desk to bring you high-density business insights.
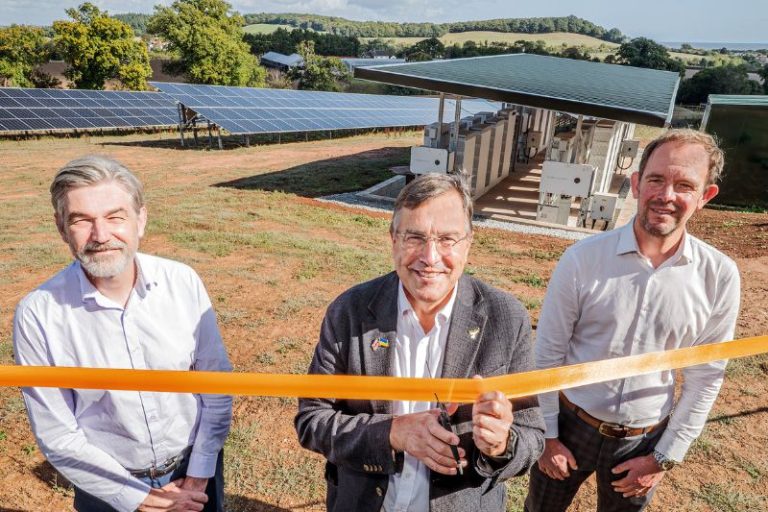
Langdon Hospital in Devon has switched on a 1.042 MW solar and battery storage system expected to meet more than 60% of the site’s annual electricity requirements.
The ground-mounted installation at the Dawlish hospital was designed and delivered by renewable energy specialist SunGift Solar, with funding provided through a national clean energy grant awarded to Devon Partnership NHS Trust by the Department for Energy Security, Net Zero and Great British Energy.
“This investment not only supports our commitment to sustainability but also ensures significant cost savings that can be redirected into enhancing patient care,” said
Phill Mantay, Chief Executive at Devon Partnership NHS Trust.
The system is forecast to generate more than 1.068 million kWh of electricity a year and reduce the Trust’s electricity costs by nearly £185,000 annually.
The system is also expected to cut carbon emissions by more than 145 tonnes a year.
The installation was officially switched on by Martin Wrigley, MP for Newton Abbot, and Phill Mantay, Chief Executive of Devon Partnership NHS Trust.
1,628-panel solar array
The solar park covers approximately 3.5 acres of land next to Langdon Hospital and comprises 1,628 JA Solar panels.
At the start of this year, JA Solar announced that its back-contact (BC) solar cells have achieved a certified conversion efficiency of 28.2%, establishing a new record for BC cell technology.
The panels are mounted on a low-carbon steel ground-mounting system supplied by Solarport, which SunGift Solar says has 66% lower embodied carbon than conventional mounting structures.
“Through the use of commercial solar cells, coupled with one of the largest battery storage installations of its kind in the UK, we have transformed a relatively small parcel of land into a hugely valuable solar asset capable of delivering the majority of the hospital’s annual electricity needs,” said Gabriel Wondrausch, Director at SunGift Solar.
The installation has a generation capacity of 1.042MWp and is designed to supply electricity directly to the hospital, reducing its reliance on power from the grid.
The project is also intended to improve resilience during periods of high electricity demand, including hot weather when demand for air conditioning increases.
Battery storage
The solar array is supported by Sigenergy hybrid inverters and SigenStack battery storage.
The batteries allow surplus electricity generated during the day to be stored and used when demand is higher or solar generation is lower.
This enables the hospital to increase its use of electricity generated on site and reduce its exposure to higher grid electricity prices during peak periods.
The system also has the potential to export surplus electricity to the grid, which could provide an additional source of income for the Trust.
The works were carried out while the hospital remained operational.
The project is expected to support Devon Partnership NHS Trust’s wider carbon reduction plans and its work towards the NHS net zero targets.
To provide the best experiences, we and our partners use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us and our partners to process personal data such as browsing behavior or unique IDs on this site and show (non-) personalized ads. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Click below to consent to the above or make granular choices. Your choices will be applied to this site only. You can change your settings at any time, including withdrawing your consent, by using the toggles on the Cookie Policy, or by clicking on the manage consent button at the bottom of the screen.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.